The question
As a Research Assistant at UGA's Multispectral Imagery Lab (advised by Dr. Thirimachos Bourlai), I set out to answer a practical question: how do five pretrained face-verification models actually compare on accuracy, false acceptance, and false rejection when you run them through the same evaluation framework?
The goal was never to build a new face-recognition algorithm. It was to treat five well-known models — VGG-Face, ArcFace, FaceNet, FaceNet512, and OpenFace — as black boxes, run them through an identical pipeline on the same 50,000 image pairs, and find out which one actually holds up.
Dataset and approach
Everything runs on Labeled Faces in the Wild (LFW) — 13,233 unconstrained face photos of 5,749 people, collected from the web with natural variation in pose, lighting, expression, and occlusion. From the full set, I selected every identity with at least 3 images, giving 901 people and 7,606 images to work with.
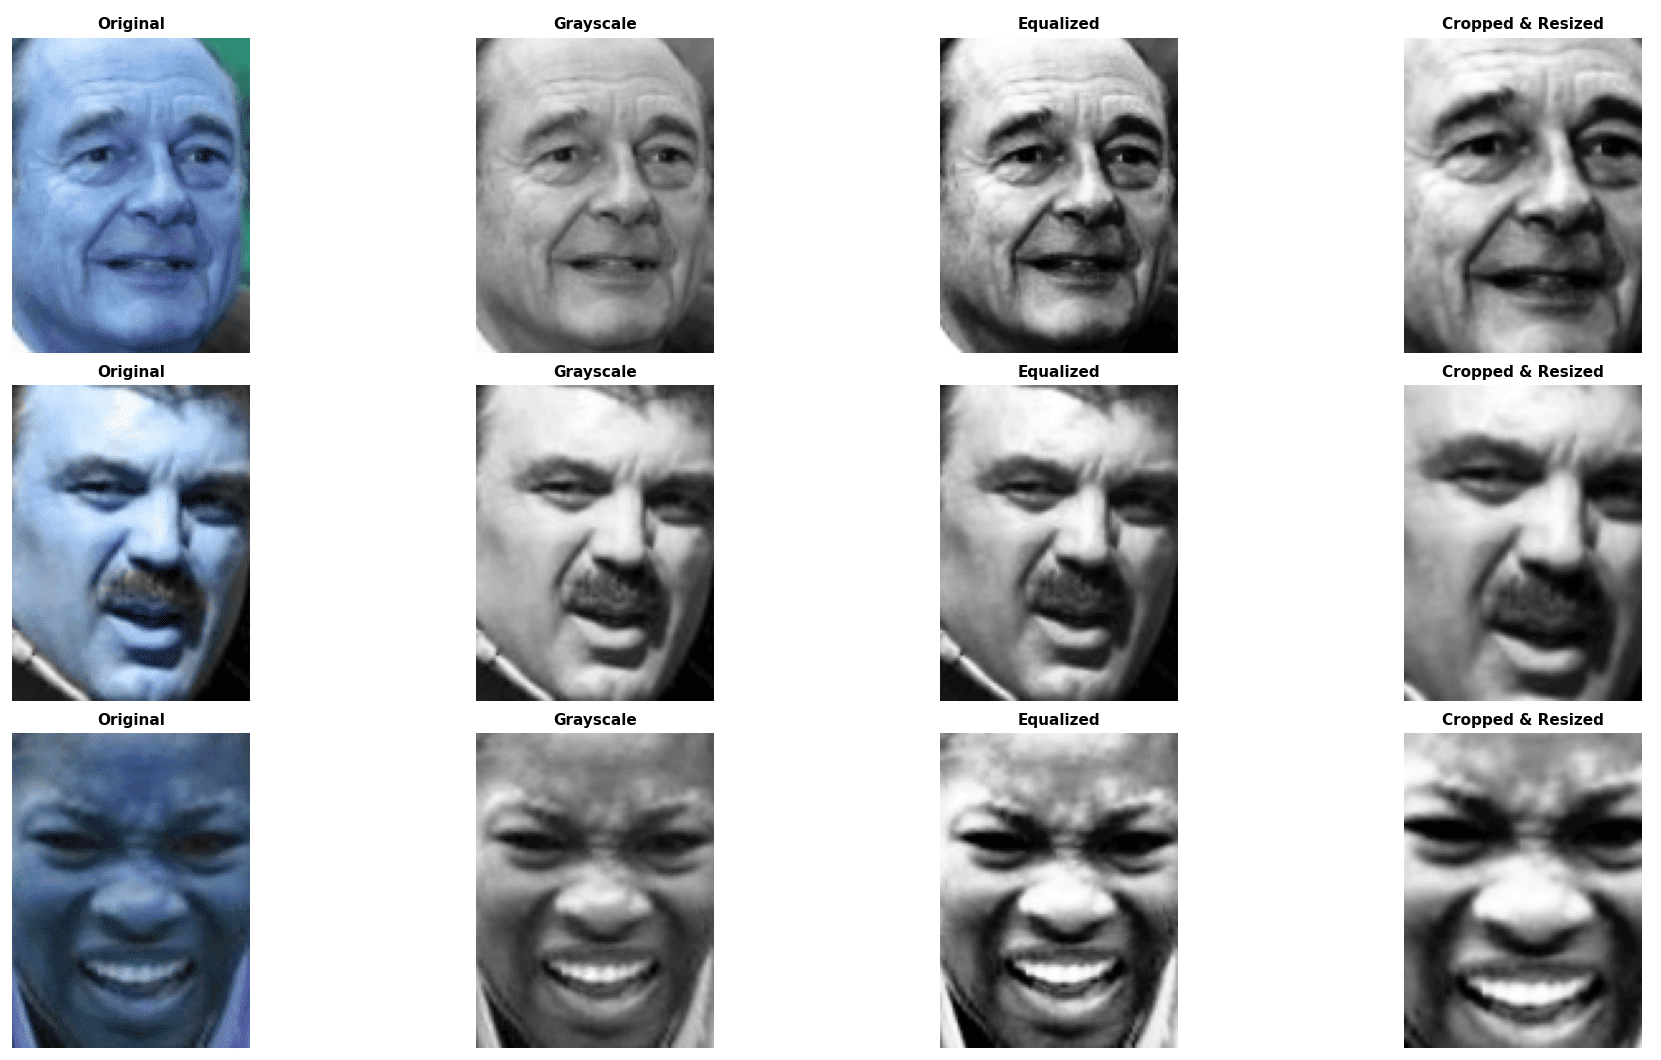
From that pool I generated 15,235 image pairs: 6,225 genuine (same person) and 9,010 impostor (different people), with a duplicate check on every pair so the same comparison never got counted twice. The full pipeline: preprocessing (grayscale, rotation correction, cropping) → face detection (OpenCV) → feature extraction (each model's pretrained embedding) → cosine-distance comparison → accept/reject against a threshold.
Getting the pipeline right first
Before scaling up, I ran the pipeline on a small custom set — my own photos against public figures — to sanity-check basic behavior. One early result mattered more than the rest: with enforce_detection turned off, an image where no face could be detected still got compared, treating the entire frame as "the face." That reliably produced a false verdict no matter who was actually in the photo.
That finding changed the entire evaluation design — enforce_detection was set to True for every subsequent test, and any pair where a face couldn't be found was skipped rather than forced through. A 100-pair pilot on LFW (50 genuine, 50 impostor) confirmed the pipeline worked before committing to the full run: 96% accuracy, 0% FRR, 8% FAR.
Large-scale evaluation: 15,235 pairs
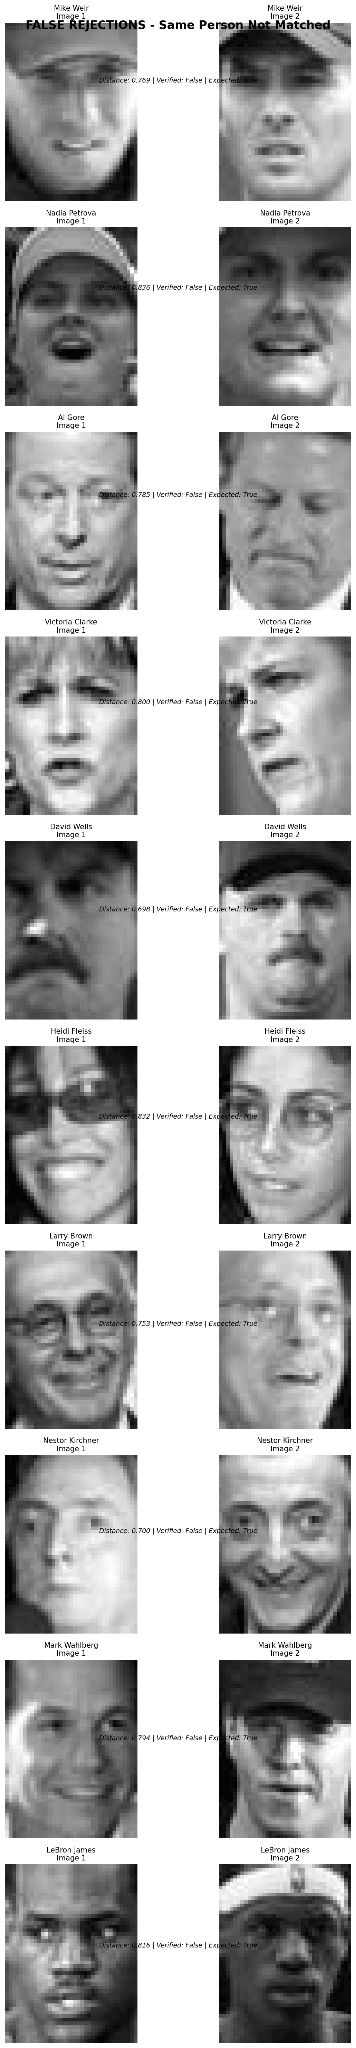
Running ArcFace across the full 15,235-pair set (901 identities, 7,606 images) gave 94.87% accuracy, a 10.55% false-rejection rate, and a 1.39% false-acceptance rate. In plain terms: about 1 in 10 genuine matches got rejected, mostly from pose changes, occlusion (glasses, hats), and lighting differences between photos of the same person — while the system stayed conservative about accepting impostors.
Looking at the actual error cases makes the failure modes concrete rather than abstract statistics.
The other kind of error
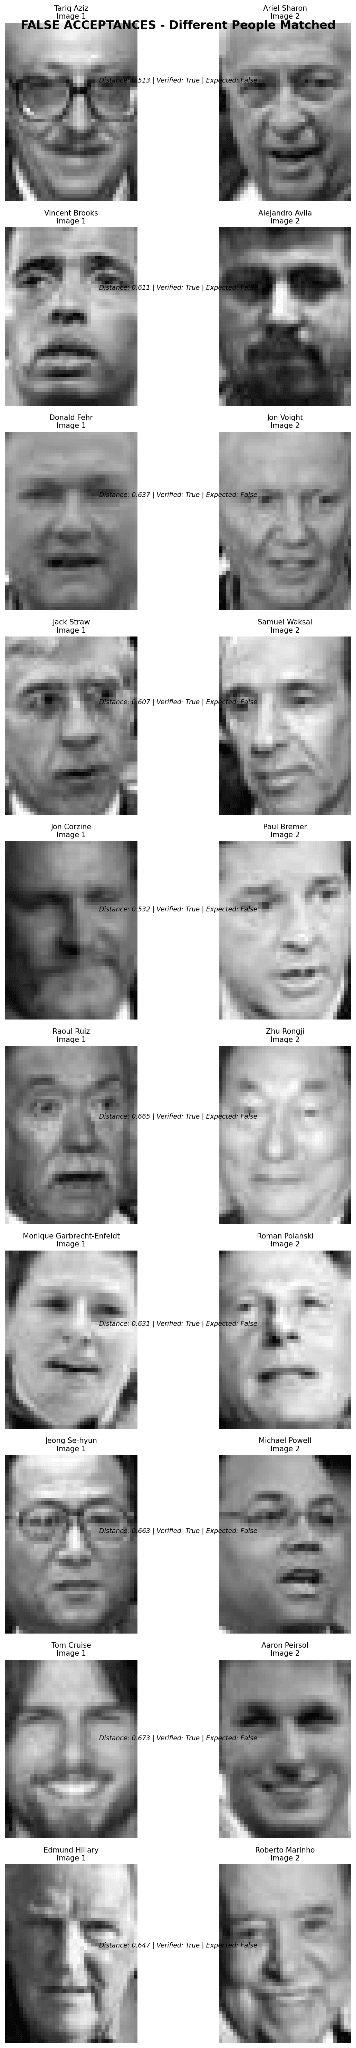
False acceptances tell a different story — mostly pairs where facial features were partially obscured, resolution was low, or two different people simply shared enough structural similarity under similar lighting to fool the embedding.
Model comparison — 5 models, 10 runs each, 50,000 pairs
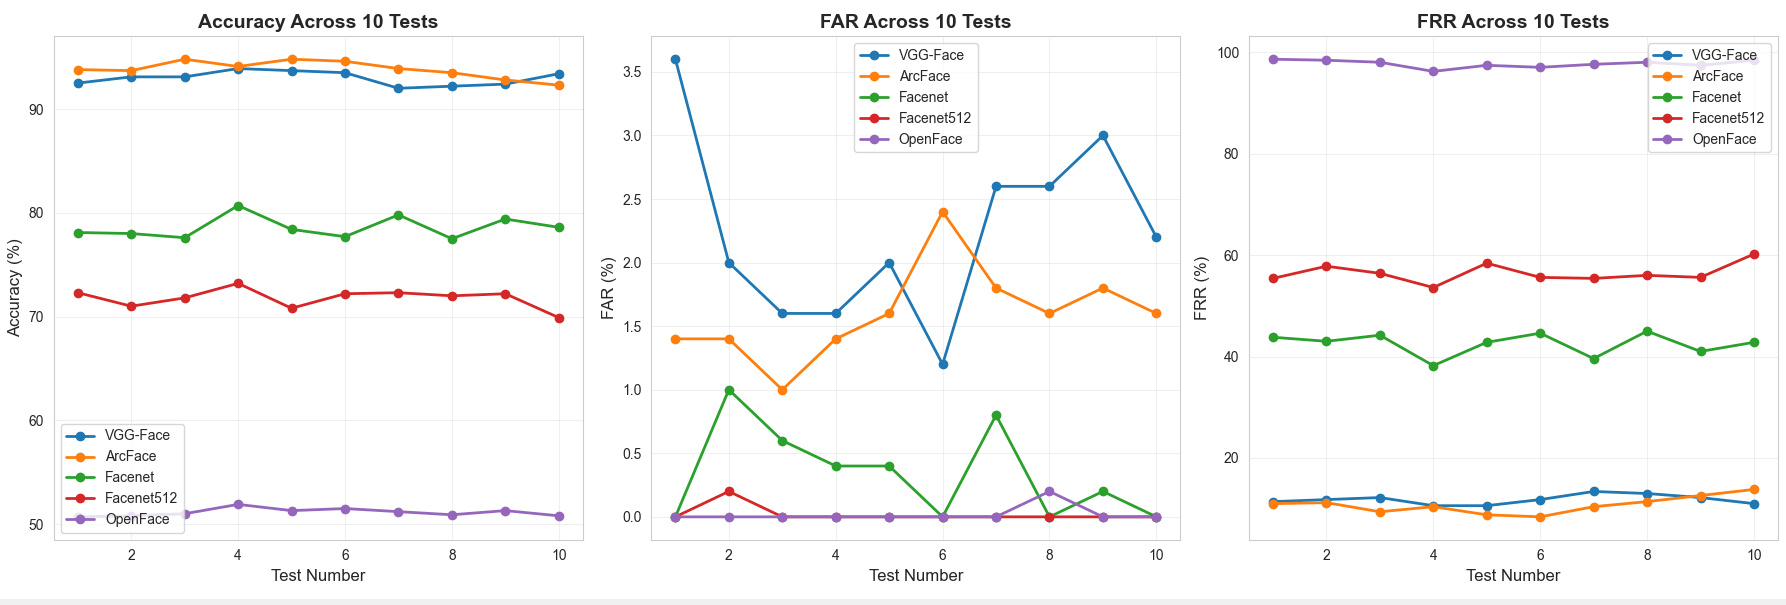
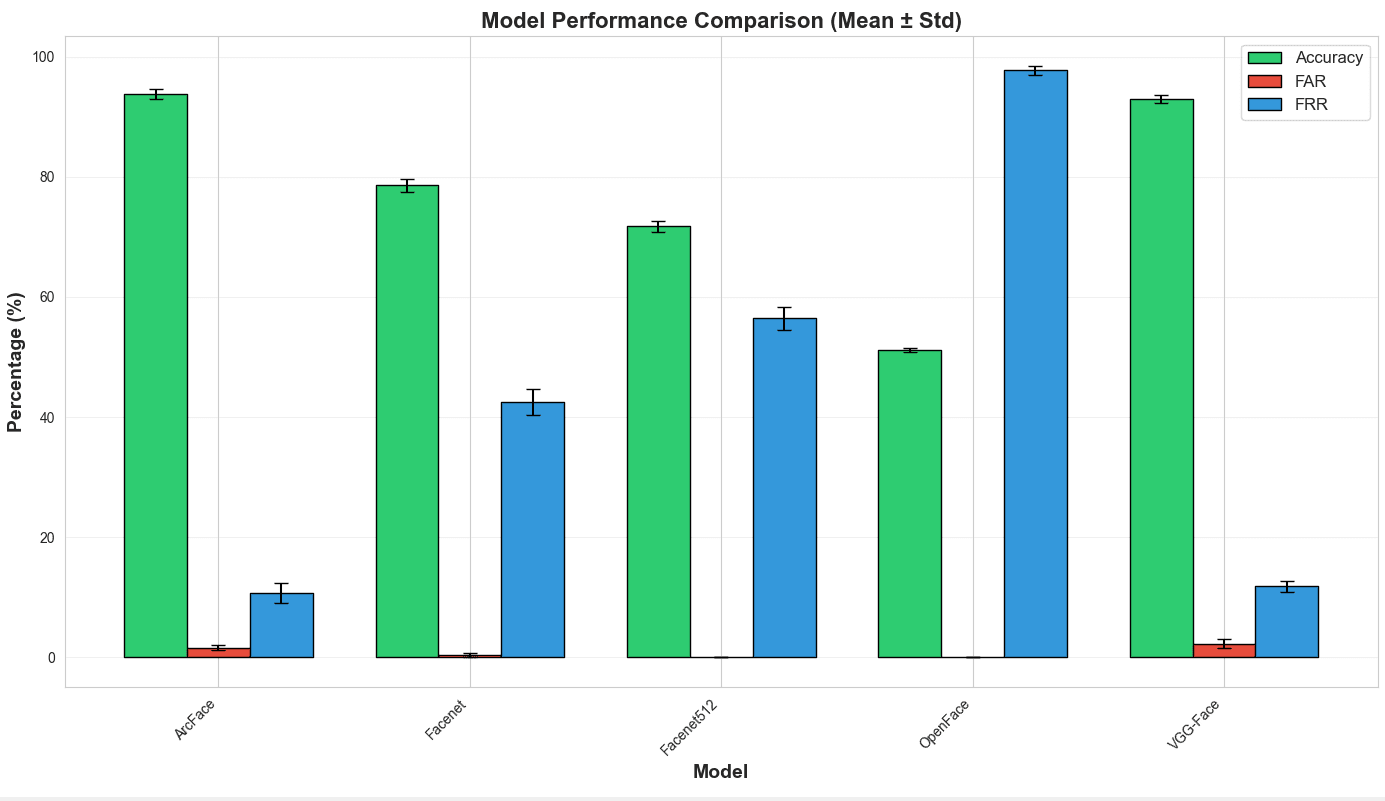
The core experiment: VGG-Face, ArcFace, FaceNet, FaceNet512, and OpenFace, each run 10 independent times over 1,000 randomly-sampled pairs per run — 50,000 verification evaluations total, at each model's own default threshold.
| Model | Avg Accuracy | Avg FAR | Avg FRR | Avg Time |
|---|---|---|---|---|
| ArcFace | 93.8% | 1.6% | 10.7% | ~610s |
| VGG-Face | 93.0% | 2.1% | 11.4% | ~470s |
| FaceNet | ~56% | 0.3% | 42.5% | ~780s |
| FaceNet512 | ~56% | 0.3% | 42.5% | ~780s |
| OpenFace | 51.1% | ~0% | ~97% | ~290s |
Why the gap is so large
ArcFace came out on top with the best balance of accuracy, FAR, and FRR, and low run-to-run variance — meaning it generalizes well across random subsets of the data, not just one lucky sample. VGG-Face was a close, faster second. FaceNet and FaceNet512 were the surprise: both rejected over 40% of genuine pairs at their default thresholds, which is impractical however low their FAR looked on paper. OpenFace effectively rejected almost everyone (97% FRR) — functioning as close to a random rejector as a "working" system can get.
This was the most counterintuitive finding of the whole project: FaceNet is widely cited as high-performing, but its triplet-loss training pushes different identities aggressively far apart — great for strict security contexts, badly mismatched to LFW's pose and lighting variation.
Threshold tuning
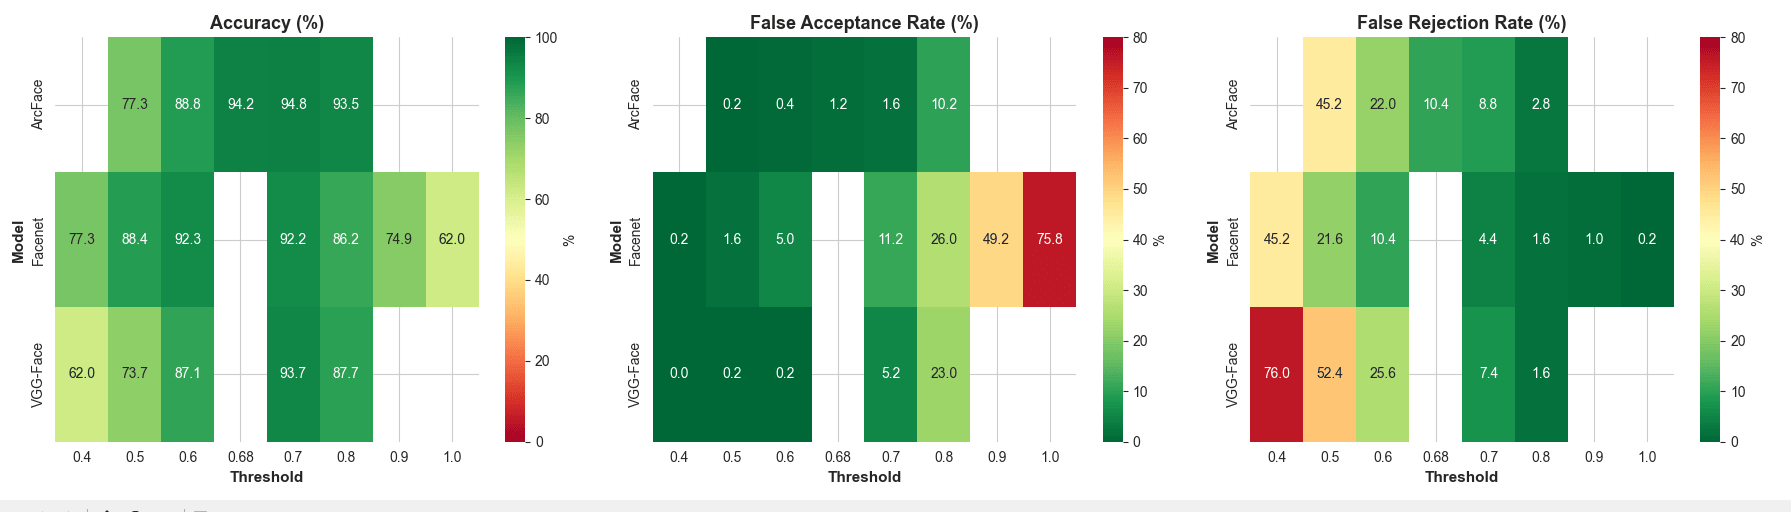
Default thresholds are tuned on whatever dataset each model was originally trained on, not on LFW. So I swept threshold values for ArcFace, FaceNet, and VGG-Face and tracked how accuracy, FAR, and FRR moved together, to find where each model actually balances on this dataset.
| Model | Optimal Threshold | Accuracy | FAR | FRR |
|---|---|---|---|---|
| ArcFace | 0.70 | 94.8% | 1.6% | 8.8% |
| FaceNet | 0.60 | 92.3% | 5.0% | ~12% |
| VGG-Face | 0.70 | 93.7% | 5.2% | ~9% |
What tuning actually bought
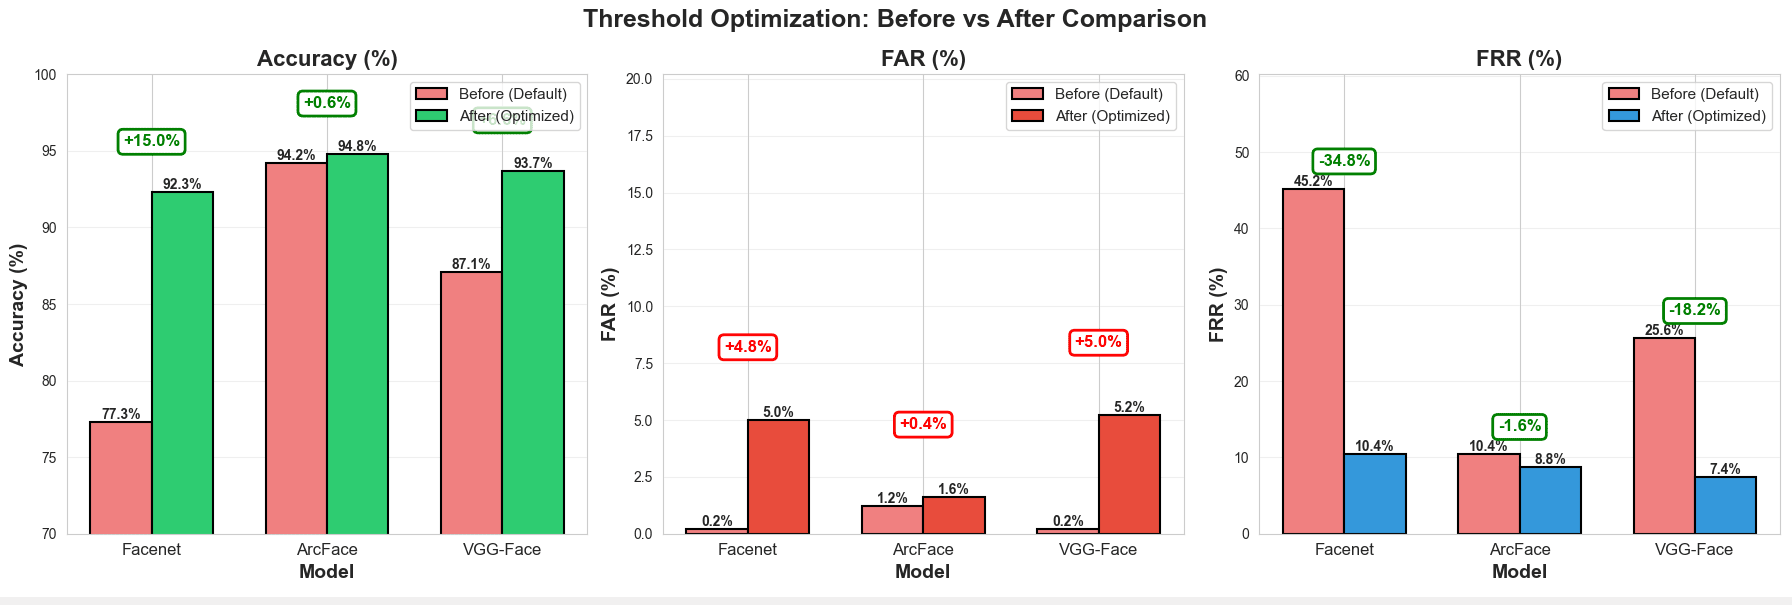
After tuning, ArcFace at 0.70 improved from 93.8% to 94.8% accuracy while cutting its FRR from 10.7% down to 8.8% — more genuine users correctly let through, with almost no added security risk. FaceNet's accuracy jumped the most (its default threshold was badly miscalibrated for LFW), but that came at the cost of a 5.0% FAR, worse than ArcFace's. VGG-Face improved similarly but landed at a less favorable 5.2% FAR.
The takeaway generalizes past this one dataset: a model's out-of-the-box threshold is tuned for whatever benchmark its authors used, not necessarily yours — any real deployment needs its own calibration step.
ROC curve — how good is ArcFace, really?
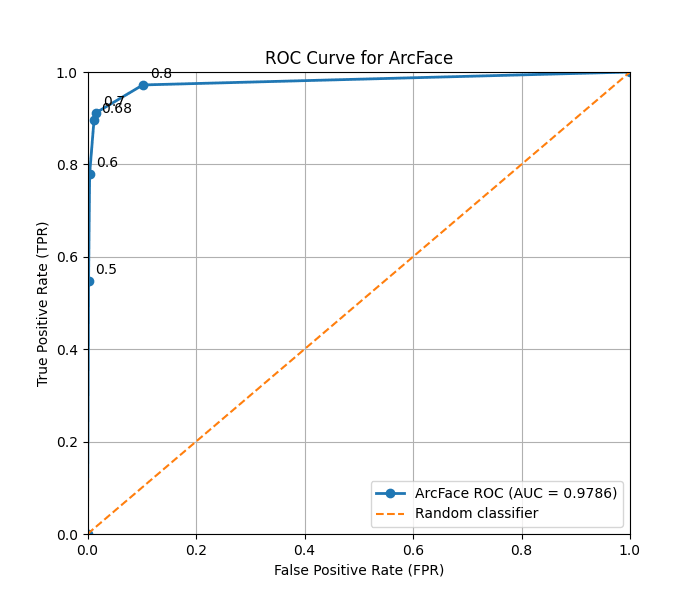
To evaluate ArcFace independent of any single threshold choice, I plotted a full ROC curve — true positive rate against false positive rate across every tested threshold. The result: AUC = 0.9786, meaning ArcFace correctly ranks a genuine pair above an impostor pair 97.86% of the time, across the entire operating range. That's a strong result for an uncontrolled, real-world benchmark like LFW.
The selected operating point (threshold 0.70) sits at 91.2% TPR and 1.6% FPR — near the curve's knee, where you can't meaningfully trade more security for more usability or vice versa without giving something up.
Where errors actually come from
Pose variation was the single biggest driver of false rejections — a frontal photo compared against a profile or three-quarter view of the same person, which OpenCV's detector handles poorly. Accessories (glasses, hats, masks) caused both kinds of error: rejections when present in only one photo, occasional false acceptances when they dominated the embedding. Poor lighting (backlight, heavy shadow, low exposure) pushed genuine pairs' embeddings apart enough to read as different people.
Two engineering lessons stood out. First, enforce_detection is not a minor setting — forcing detection on an undetectable face silently corrupts results rather than failing loudly. Second, aggregate accuracy alone hides the real story: FAR and FRR are different failure modes (security risk vs. usability risk) and have to be read together, which is exactly what the ROC and threshold-sweep analysis were for.
Limitations
No liveness detection — a printed photo or screen replay could plausibly spoof this system, and that was never tested. Everything ran on static images; there's no evaluation on video, near-infrared, or thermal imagery. All five models were used strictly as black boxes with zero fine-tuning, which likely caps performance below what a domain-adapted version could reach. And this is a single-dataset result — LFW has known demographic imbalance and a heavy skew toward celebrity photos, so these numbers may not transfer cleanly to a different population or capture setup.
Future work
Fine-tuning ArcFace on a domain-specific dataset to push FRR down further; adding a liveness-detection stage to close the spoofing gap; validating against additional benchmarks (VGGFace2, IJB-C) to check whether these findings generalize; a more rigorous demographic fairness analysis with actual statistical testing; and trying alternative detector backends (RetinaFace, MTCNN) that may handle difficult poses better than the OpenCV Haar cascade used here.
Closing
Across 50,000 verification runs on real, unconstrained photos, ArcFace with a tuned threshold of 0.70 was the clear, reproducible winner for this dataset and task. But the more durable finding is procedural: a face-verification system's reported accuracy means very little without knowing its FAR/FRR trade-off, whether its threshold was calibrated for your actual data, and what its failure modes look like when you go looking for them.
Full source code (pair generation, model comparison, threshold tuning, all scripts) is available at github.com/Linsanity12/face-recognition-uga.